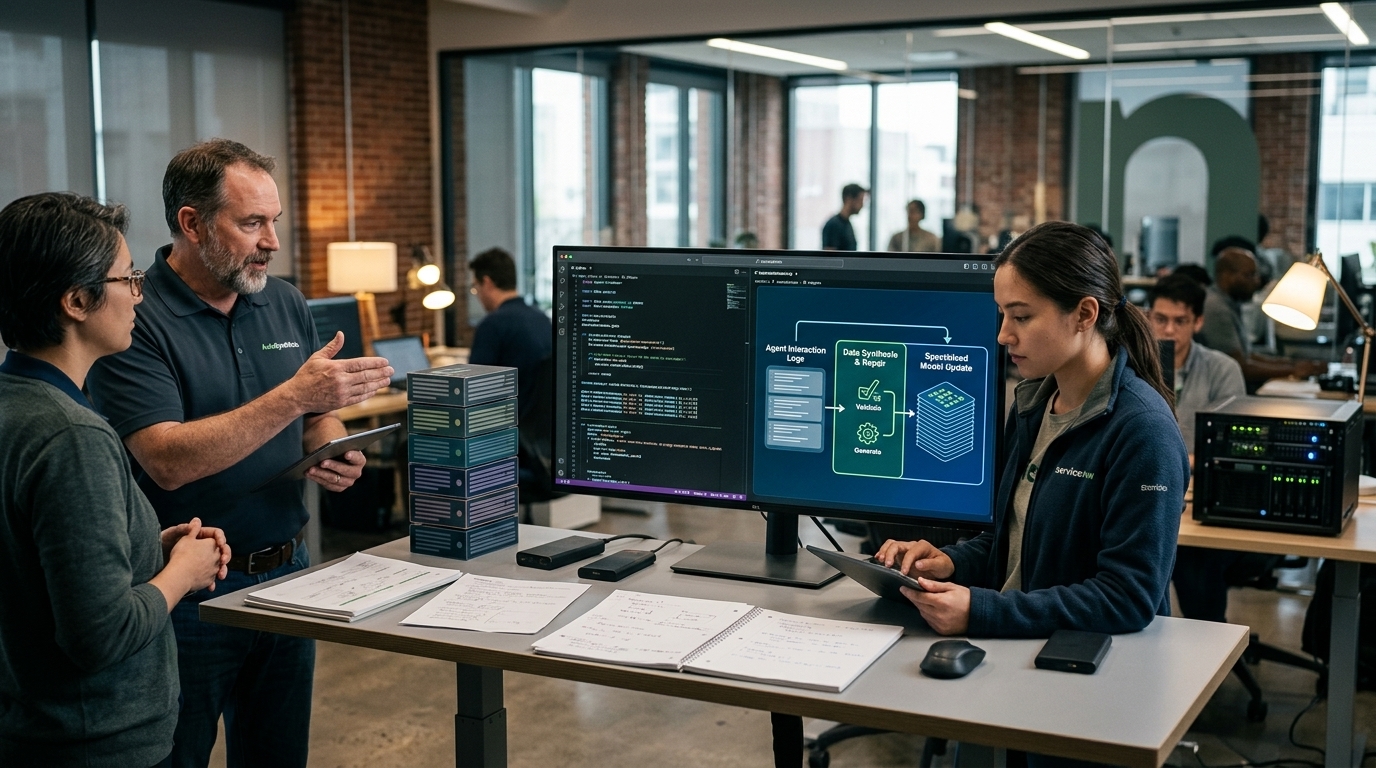
Enterprises increasingly require AI agents tailored to their unique operational environments. While large models are broadly capable, they often falter when faced with specific corporate workflows, tool combinations, or policy constraints. To address this, ServiceNow CoreAI has developed AutoSynthData, a pipeline designed to turn these capability gaps into high-quality training data.
The Synthetic Training Architecture
AutoSynthData functions by evaluating a target model against a stronger "teacher" model to identify specific failure patterns. These gaps are distilled into capability specification cards, which guide the generation of new tasks. According to the researchers, a useful task must satisfy three properties: feasibility (it must be solvable within the environment), realism (it must resemble actual user requests), and difficulty (it must target a known weakness of the agent).
Multi-Level Quality Control
Generating plausible requests is insufficient for effective training; the data must be rigorously validated. AutoSynthData employs a two-tier review process:
- Sample-level verification: A "positive gate" ensures the reference solution works, while a "negative gate" confirms that incorrect outcomes are properly rejected.
- Batch-level meta-review: This process monitors diversity and coverage, preventing the dataset from becoming repetitive or over-representing easy tasks.
The pipeline also includes a "critic" mechanism that diagnoses failed candidates and attempts to repair them before they are discarded, maximizing the yield of the generation process.
Proven Performance Gains
Experimental results using the EnterpriseOps Gym benchmark demonstrate the pipeline's efficacy. In the Hybrid domain, a Gemma-based model fine-tuned on 2,000 AutoSynthData samples saw a 35% relative improvement in its Pass@1 metric. Similar success was observed in the ITSM domain, where success rates climbed from 18.77% to 27.18%, closing a significant portion of the performance gap compared to reference models.