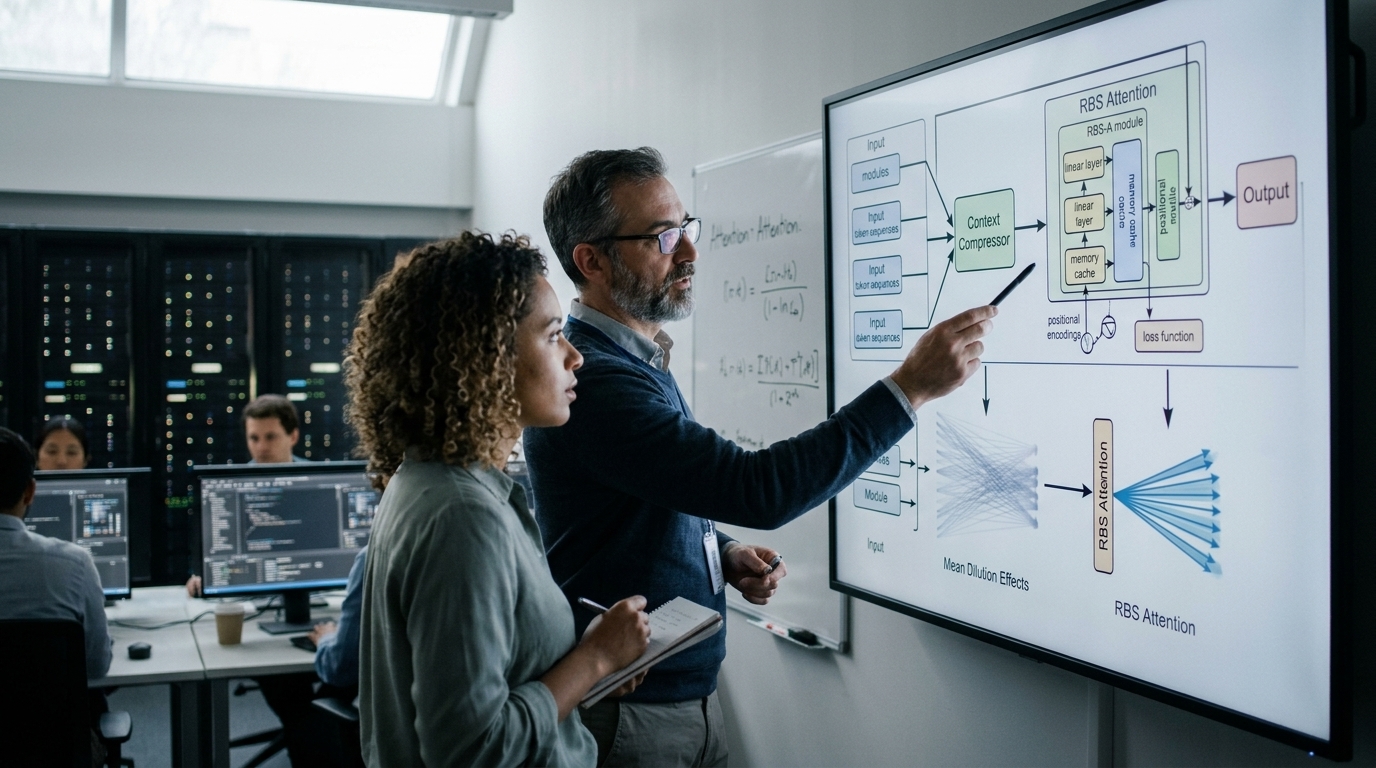
Inference for long-context large language models (LLMs) is increasingly bottlenecked by the prefill stage, where dense self-attention processes the entire prompt before generation begins. Researchers have introduced RBS-Attention, a training-free sparse-prefill method designed to mitigate a specific failure mode known as "mean dilution."
Addressing Mean Dilution
Mean dilution occurs when a block centroid hides a highly relevant token among many irrelevant ones, causing standard sparse selection methods to overlook critical information. RBS-Attention addresses this through a dual-branch selection mechanism:
- Centroid Base Branch: Captures the average relevance of blocks.
- Rescue Branch: Utilizes the maximum key-block radius and its specific distribution (dependent on prompt, layer, and head) to identify blocks at risk of underestimation.
Performance Benchmarks
Testing on H100 GPUs using the Qwen3-30B-A3B-Instruct-2507-FP8 model at a 128K context window demonstrated significant efficiency gains:
- 20.65x standalone prefill-attention speedup.
- 11.92x vLLM prefill-attention speedup.
- 5.97x end-to-end time-to-first-token (TTFT) speedup.
Regarding model quality, RBS-Attention maintains high performance levels. On the dense Qwen3-32B model, it achieved an 88.65 overall RULER accuracy, compared to 89.52 for standard dense attention. The method was further validated using benchmarks such as LongBench-v2, InfiniteBench, and Video-MME, supporting radius-adaptive dual-branch selection as a viable path for long-context optimization.