Traditional guardrail systems for large language model (LLM) agents typically function as binary classifiers. When unsafe content is detected, it is simply blocked, forcing organizations to discard the output and restart the generation process from scratch. New research published on arXiv introduces RAIL Guard, a closed-loop responsible AI pipeline designed to bridge this efficiency gap.
The Evaluate-Rewrite-Reevaluate Loop
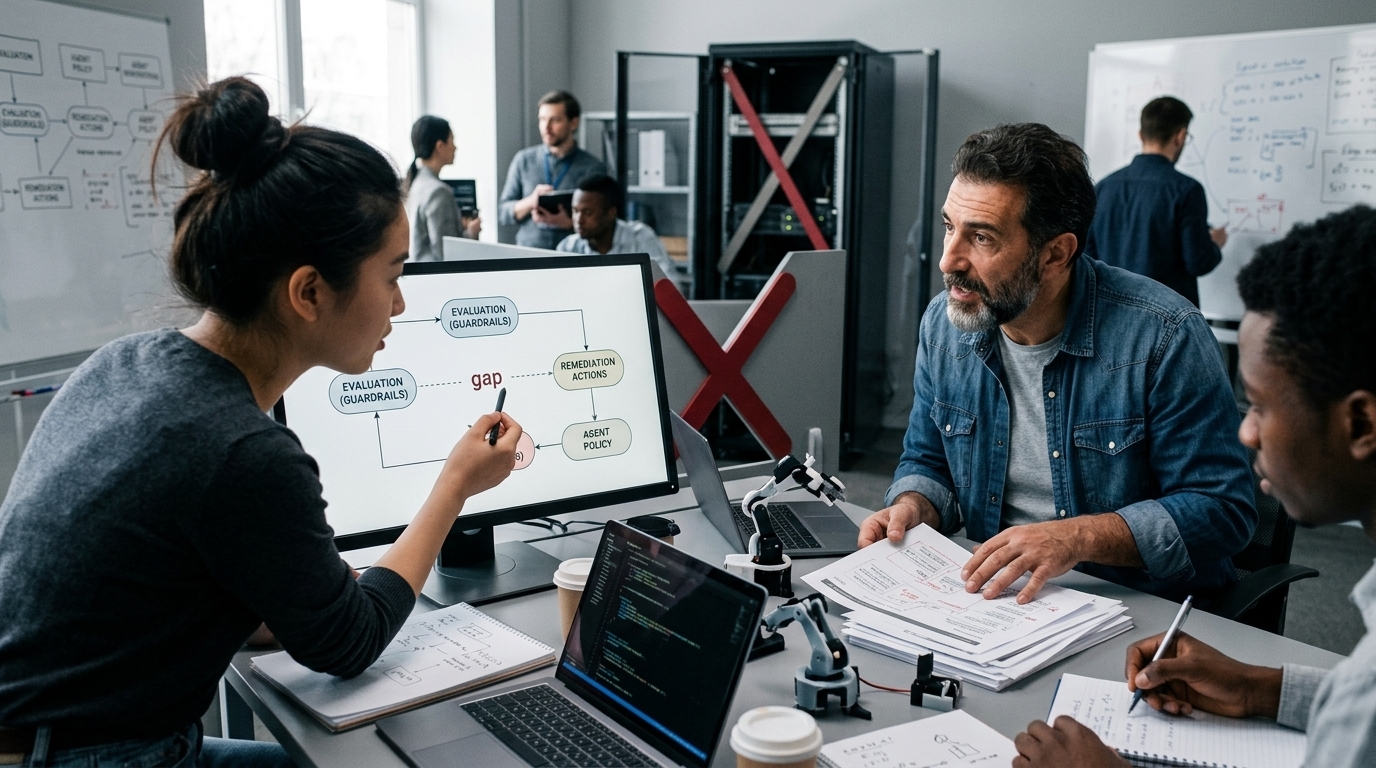
RAIL Guard evaluates LLM outputs across eight distinct measurable dimensions. Rather than terminating a process upon failure, it initiates an iterative "evaluate-rewrite-reevaluate" loop to remediate the output. Testing across four frontier LLMs and 4,276 content outputs revealed significant improvements:
- Closed-loop remediation achieved a 96.9% convergence rate, compared to 49.1% for the standard block-and-retry approach.
- Feedback-driven self-repair reached 86.6% convergence on fixable dimensions with no statistically significant loss in utility (p = 0.177).
- Pre-tool-call evaluation reduced unsafe agent executions by 33% (p = 0.007) while maintaining a zero-impact rate on task completion.
Structural vs. Algorithmic Challenges
The study identifies a vital distinction between "fixable" dimensions and "structural" ones. While the pipeline excels at refining specific content errors, structural dimensions such as Transparency (93.0% failure), Accountability (92.8%), and Inclusivity (82.5%) remain resistant to simple remediation loops. These areas, according to the researchers, require fundamental architectural changes rather than algorithmic patches. The RAIL Guard system has been released as open-source SDKs for the developer community.