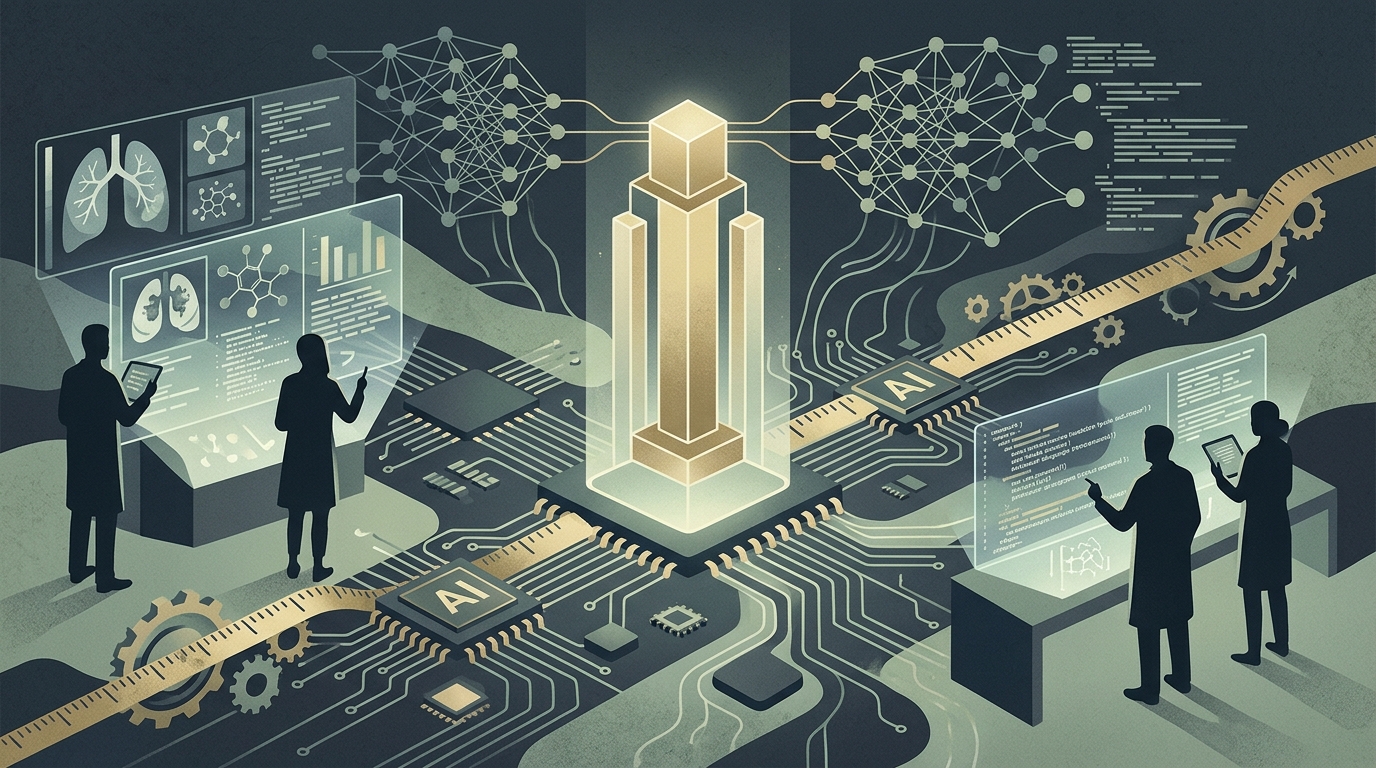
As we navigate the mid-point of 2026, the integration of Artificial Intelligence into clinical workflows has shifted from speculative research to an infrastructural necessity. A pivotal new study released on ArXiv (cs.AI, 2606.28556), titled "IMCBench: A benchmark for multimodal LLMs in Image-grounded Medical Conversations," addresses a fundamental bottleneck in the field: the lack of a standardized, robust framework to evaluate Multimodal Large Language Models (MLLMs) in complex, image-centric clinical dialogues.
Traditional benchmarks have largely focused on Visual Question Answering (VQA), where a model provides a single answer to a single question about an image. However, clinical reality is far more nuanced. Diagnosis is a multi-turn process where information is gathered, refined, and debated. IMCBench introduces a dynamic testing environment that measures how well an AI can sustain a medical conversation while being strictly 'grounded' in visual evidence such as X-rays, MRIs, and CT scans.
The Critical Need for Contextual Grounding
The core issue with modern MLLMs—even those as sophisticated as GPT-5 or the latest Med-PaLM iterations—is the risk of 'un-grounded' reasoning. A model might possess vast theoretical knowledge of oncology but fail to correctly map that knowledge onto the specific pixels of a patient's scan. IMCBench challenges models to not only identify anomalies but to discuss them within the context of a patient's history and ongoing clinical queries.
The benchmark evaluates models across three primary dimensions: visual perception accuracy, the logical coherence of medical reasoning, and the safety of the clinical advice provided. A major focus is placed on mitigating 'hallucinations'—instances where the AI identifies a pathology that does not exist. In a high-stakes environment like a hospital, these errors are not merely bugs; they are potential clinical disasters. By quantifying these failures, IMCBench provides a clear metric for improvement.
Methodology: Beyond Simple Q&A
The researchers behind IMCBench curated a diverse dataset involving thousands of medical images paired with expert-annotated, multi-turn dialogues. These conversations simulate real-world interactions between primary care physicians and specialists, or between doctors and AI assistants. The models are tested on their ability to:
- Maintain Context: Tracking specific findings across multiple turns of a conversation without losing the thread.
- Reason Spatially: Accurately describing the location and extent of a lesion or fracture as depicted in the image.
- Adhere to Protocols: Ensuring that recommendations for further testing or treatment follow established medical guidelines.
One of the most striking findings from the initial tests using IMCBench is the performance gap in specialized domains. While general-purpose models perform admirably on common conditions, they often stumble when faced with rare pathologies or complex histological slides. This reinforces the argument that the future of medical AI lies in domain-specific fine-tuning rather than broad, generalist capabilities.
Implications for the Healthcare Industry
The release of IMCBench is timely, coinciding with increased regulatory scrutiny under frameworks like the EU AI Act. For healthcare providers, the benchmark offers a transparent way to vet AI tools before deployment. It moves the industry away from 'black box' claims of accuracy and toward a verifiable standard of clinical competence.
Furthermore, IMCBench facilitates a better understanding of the human-AI interface. By evaluating how an AI explains its reasoning during a conversation, developers can create tools that are more intuitive for doctors to use. The goal is not to replace the clinician but to provide a 'second pair of eyes' that can articulate its findings clearly and reliably.
Conclusion: The Road to Clinical Trust
In conclusion, IMCBench represents a significant leap forward in the quest for reliable medical AI. By shifting the focus from static image labeling to dynamic, grounded conversation, it mirrors the complexity of human medicine. As we look toward 2027, the benchmarks we establish today will be the foundation of the trust patients and doctors place in these systems. IMCBench ensures that this trust is earned through rigorous, transparent, and clinically relevant evaluation.